Published
- 14 min read
A Journey without Destination: My Experience with Research
It was the early morning of 9th February 2025, we were all in a hostel room, with a dim, cozy, yellow light turned on, having a conversaion about acads and future plans. As the 2nd year was ending, the lab scouting season had just begun: students looked for research labs to join and advisors to choose for the next 2 to 3 years. My friends enrolled in research oriented degrees were discussing potential labs to join, like RRC, PreCog, CVIT, LTRC, etc. PreCog particularly stood out to me - it had really approachable and accomplished seniors. PreCog is different from other labs in the college: there is only one Professor, Ponnurangam Kumaraguru (aka PK), in the lab and, notably, it is one of the few labs which had an assessment and a round of interview before joining.
The joining assessment had been open for the past few weeks and some of my friends were applying to the lab. Jokingly, one of my friends suggested that I apply for the lab and finish the assessment. The only issue? The assessment was released about 460 hours ago, and the deadline was in 44 hours, on the eve of my 20th Birthday.
The Race Against Time
I went through the assessment, and almost immediately one of the tasks seemed really interesting to me. It was about making a model reason better and improve the performance at the SED game puzzle. I treated this task as a challenge and tried multiple methods for improving performance, including a novel idea (I coined it to be Sherlock and Watson Approach) where the Sherlock model reasons and tries to arrive at the solution, while the Watson model periodically oversees the thought process, notes what worked and what failed, and guides the Sherlock model in the right direction. After countless, caffeine fueled hours of tweaking parameters and drafting up a barely put together report, I managed to submit my files at 12:30am, about 30 minutes after the deadline, and also 30 minutes into my birthday, with my friends being annoyed at me being late to my own birthday celebration.
As it turned out, the seniors at PreCog liked the Sherlock and Watson idea and I was shortlisted for the interview. In the interview I was asked to explain my approach and intuition behind it along with the code and my plans to do research in PreCog. I was really nervous yet confident in my solutions and replies. Following a few weeks of anxious waiting we finally got the results. I had successfully cleared the interview round and was officially part of PreCog!
So… what exactly is research?
Since I was an undergraduate student, I had very limited prior experience with research and technical writing. The seniors at PreCog hosted a week-long induction session which allowed us to get started with research, from understanding what conferences are to writing and debugging basic PyTorch code, this gave us the much needed exposure to research.
During this month, I also actively started trying to consume more research materials, may it be a seminal work of research, or a guide on how to get started with research and figure out which problem statements to tackle. This mapping out of the field was really important and allowed me to have a better understanding of the domain, which provided me with confidence to ask PK (my research advisor) about starting a new project.
PK put me in touch with two accomplished research scientist volunteers working with ANRF — Rahul and Lakshmanan — to build Pragyan, an AI Assistant for reviewing research grant proposals. The goal was to develop a tool that will be used by ANRF (Government body established to provide strategic direction for scientific research, innovation, and entreprenurship). Though this was not an actual research project with potential paper submission, I worked on this for the next couple of months, iteratively improving and implementing new features and grounding the model responses.
Starting a new project
As our summer vacation was about to end, and the 3rd Year of college was about to begin, PK connected me, and two labmates, Sudarshan and Sushant, with Prof. Chirag from The University of Virginia (UVA) to start working on a new project collaboration. Chirag had an interesting direction in mind, to improve current Multimodal Explanability (MxAI) Methods. These are algorithms which allow us to understand what features a multimodal model relied on for a given input and model output.
In the following meetings we were trying to hypothesize what the current MxAI Methods were lacking and how we could improve them. Thus we started a thorough review on currently existing literature (aka lit review) to find a “gap”. A month passed and we had a decent understanding of the field and sorrounding literature. We were about to start tackling the research problem and attempt at developing a better MxAI Algorithm.
But wait, wdym “better”
In one of our weekly meetings, a point of discussion came up: we want to make better MxAI Algorithms, but how do we objectively define the word “better”? Our postulation was that more faithful the output MxAI Method to the model’s true reasoning, the better the algorithm. But this brings up another question, how do we measure the faithfulness of an Explanability Algorithm? Little did we know, that this soon became the problem we would tackle instead.
Turns out that it is not a trivial question to answer, I would say that our major research contribution was answering this question. The complexity arises from the fact that to measure the faithfulness of an explanability method, we need to know what exactly a model is relying on. A slight issue: we don’t know what the model is relying on. But consider for a second, what if we knew what a model is actually relying on? We can then compare what we know about the model with the outputs of the explanability algorithm to determine their faithfulness.
Though it does sound somewhat absurd, we tried to train a model in such a way that we know what features in the input it is relying on. We hypothesized that if we have a dataset where each question had only a single path towards arriving at the solution, and the model was achieving really high performance, we can conclude that the model is using the intended path of reasoning, thereby allowing us to know what the model relied on. A core benifit of this approach was that since both model and dataset were now “fixed” all the blame could be attributed to the explanability algorithm instead of the model.
Searching For A Model That Doesn’t Exist
Initially, we started with measuring the performance of open source models on chess images to retrieve the positions and answer simple questions such as “Is there a white pawn on E5?“. But we soon found out that even the frontier models back then severely hallucinated positions and detecting pieces. No matter what model we used and how “easy” the chess position was, the model consistently failed at the task. This was not going to work. And on top of that, the model would’ve inherited learned biases from its training data that we could not account for. Thus, we decided to go with a purely synthetic dataset along with training a model completely from scratch. In hindsight, this was a really good decision as we could completely control what the model is trained on and, thus, effectively control for biases and allow for more granular analysis.
Though we were moving in the right direction, this added to the list of tasks that we needed to accomplish: 1) Develop a Dataset Satisfying Unique Ground Truths property, 2) Implement and Generate the Dataset, 3) Train a Model to achieve high performance on the Dataset, 4) Prove that our approach is mathematically logical, 5) Finally, benchmark current MxAI Algorithms.
A Brick Wall
As the Third year of college had begun, so had our intern drive. Back then, doing research was not my topmost priority, instead it was securing a good internship, and successfully bagging the full time return offer. As the intern season was in full swing, I had to give Online Assessments for a lot of companies, around 3-4 per week on average. This along with interviews, the ramping up of coursework, and the TA position I had meant lesser time to focus on research and need to compromise. This lack of time spent on doing research was clearly noticable as the progress on the project had started to slow down and the initial enthusiasm had disappeared.
We had also set some really ambitious deadlines earlier, including a submission to ICLR’26, which it had become clear we would not meet and led to further discouragement and burnout. This was around the same time my first project in PreCog, Pragyan, was put on indefinite hold and multiple months of effort had seemingly “no fruits”. This was also when my other research thread, in collaboration with AlphaGrep, was starting to ramp up and heavily shift away from the original idea.
All of this, along with me unable to land early internships on the campus drive really demotivated me to continue with research. But then I remembered a quote by Randy Pausch, “The brick walls are there for a reason. The brick walls are not there to keep us out. The brick walls are there to give us a chance to show how badly we want something. Because the brick walls are there to stop the people who don’t want it badly enough. They’re there to stop the other people.”
Breaking the Brick Wall
After talking to a lot of seniors, and my sister, Himani, I decided to focus on one thing at a time. Firstly, the campus intern drive, which ended up landing me a SWE Intern Role for Summer’26 at Teradata. This freed up a large portion in my schedule, allowing me to tackle academics and TA duties. The following month I largely focused on my academic duties, TA duties, and helping organize a large Hackathon in college with over 1200 participants.
The month of October had begun with the team gunning for the CVPR’26 deadline in mid-November.
Research Resumption
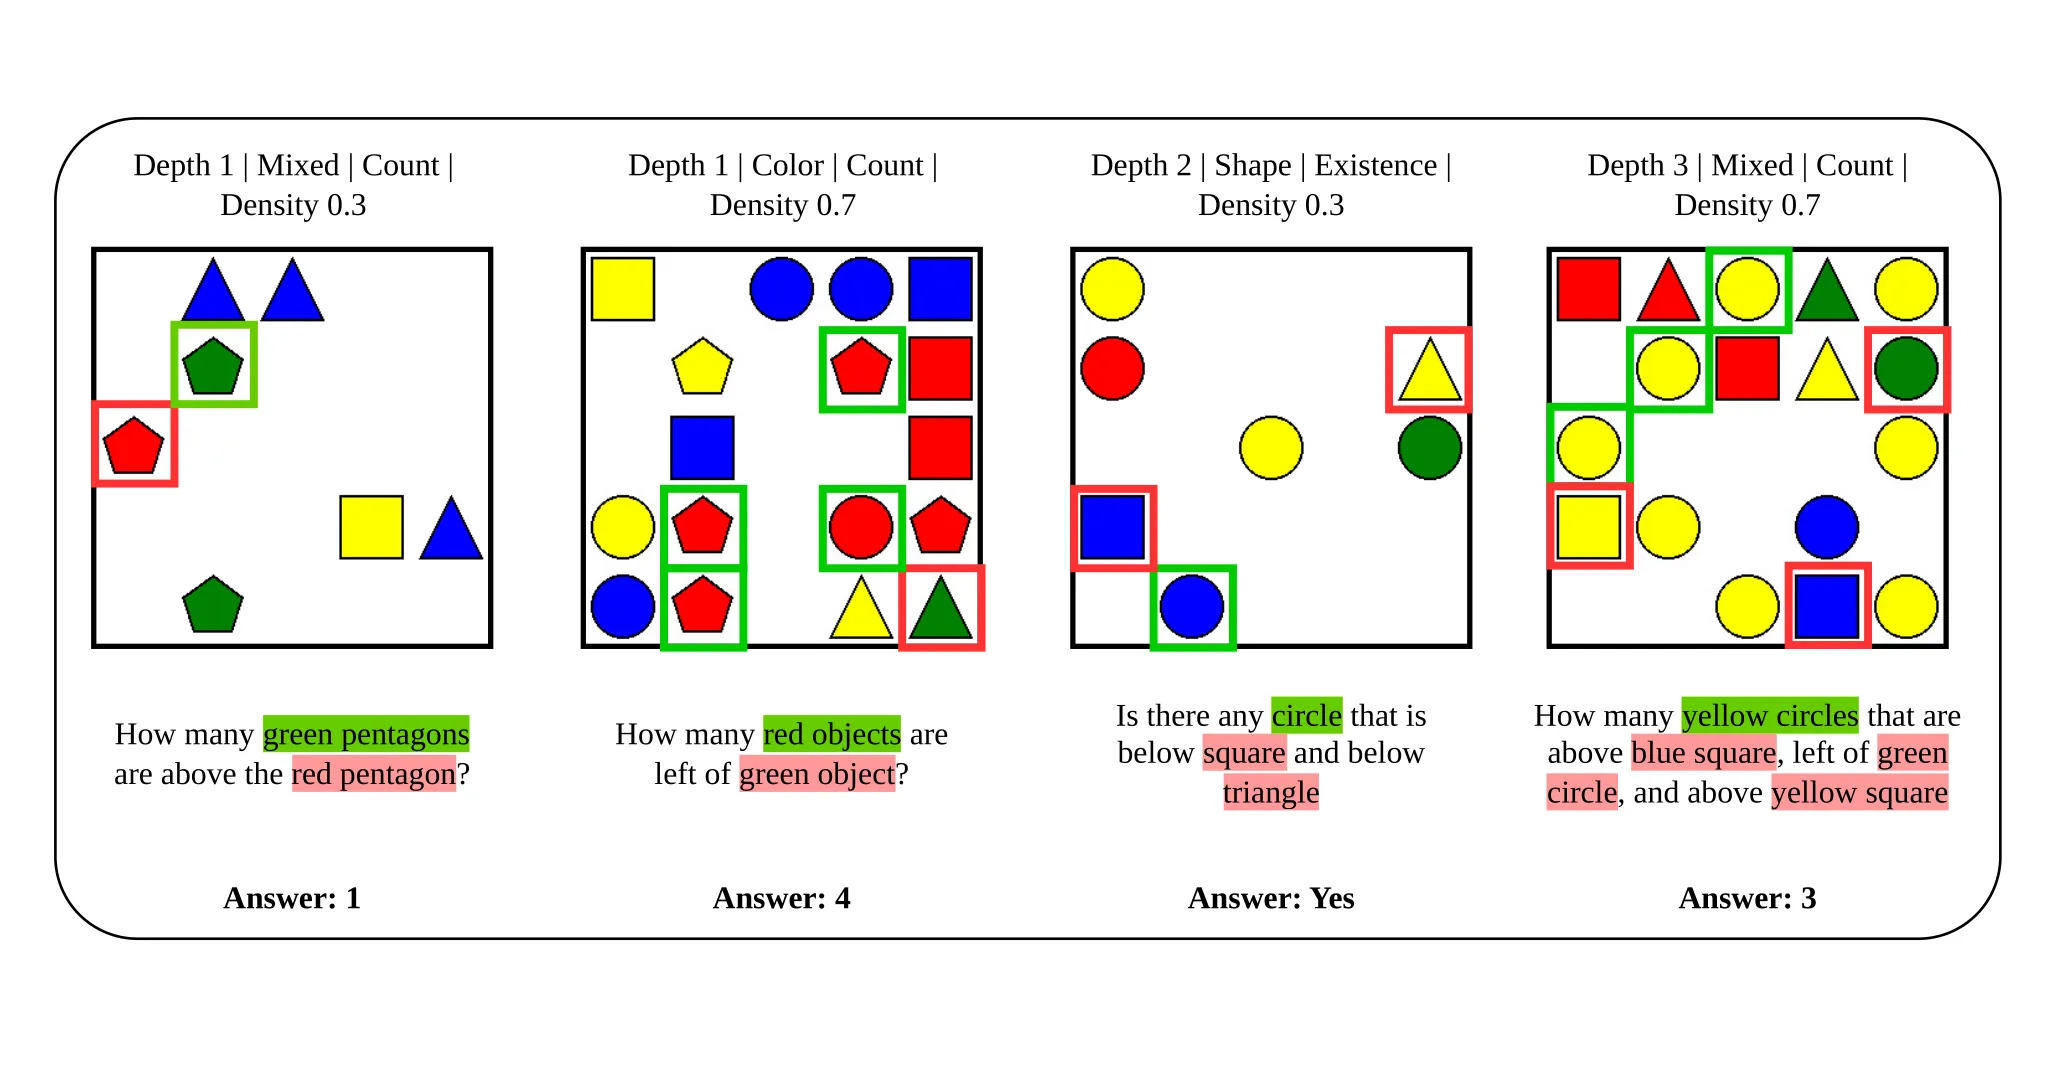
The research was progressing well, the dataset was finally taking shape (pun intended). We decided to go forward with a simple dataset of 2D images of elementary shapes along with basic questions asking model to perform spatial reasoning. We had tried our best to eleminate any shortcuts in the samples and ensure that for all queries the model had to perform spatial reasoning and come to the right answer. As October was nearing its end we were almost done with dataset generation logic and had begun with model training, which was expected to last only a few days. Apart from this, we had started implementation of published MxAI methods for benchmarking and qualitative analysis. But just a few days before the submission deadline, we discovered that the dataset had a fatal flaw: existence of shortcuts. This required a complete regeneration of dataset along with model training from scratch, which would cut it too close for submission. To avoid submission of a half-baked paper, we decided to focus on the ICML’26 Deadline at the end of Jan’2026 instead.
But this time, we had learned something: we cannot rely on “guts” and had to mathematically support the lack of shortcuts (spurious correlations) in the dataset and paper. We also developed an interesting idea: develop a dataset for spurious correlations and train a model on it. Since a model exploiting spurious correlatioins must not rely on the same ground truths as the pure model, a good MxAI algorithm must perform worse on it thus differentiating both the models. Development of both these datasets along with formalizing proofs had continued.
Unexpected Hurdle
Since all of us working on the problem were undergraduate students, the progress was explicably linked to our college schedule. As the endsems were nearing, our meetings with Profs had become less frequent and progress had slowed down. But as December had begun, we were back on track: exploring other metrics and ideas that we could use in our benchmarking framework.
We had to make significant changes to the existing MxAI Algorithms to work with our model architecture of choice, MDETR. As anyone who has previously worked with research code can attest to, it is very difficult to deal with it. A lot of the times documentation required to reproduce the results does not exist. A lot of the times, we had to make assumptions about the code’s enviornment, sometimes we even took a look at the logs of some pip commands to reverse engineer the original run’s Python and module versions. As the ICML deadline was nearing and we had not fully finished running these algorithms, we decided to target the next relavent top-tier conference instead: ECCV’2026.
Endgame
We had started to finish the running of experiments and had begun paper writing with about a month to the deadline. The month was filled with a lot of debugging, sleepless nights, and paper writing + review sessions with labmates. All was going well, according to the timeline. The abstract submission was done on time and we were on track to paper submission in about a week’s time. While carefully analyzing the results we realized a shattering mistake: the model was performing at essentially random accuracy on my GPU cluster as compared to my co-author’s GPU cluster. We had put in a large magnitude of effort over the last few months, and it had all come to this. It could not be hindered by this bug. We spent hours trying to debug, to no avail. Our lack of experience was coming back to bite us.
We decided to inform Prof. Chirag about this bug, and it was the best decision we made. Chirag was on a call with us till 4am in the morning, and his experience helped us tackle the bug and fix it with relative ease. The model was now performing as expected and the affected experiments were re-run. The next 3 days we focused on paper writing and making of figures. Finally, we were able to make the submission to ECCV’2026.
Following a month of paper refinement and running of additional experiments, we also decided to submit the paper to CVPR TRUE-V Workshop. The workshop paper was accepted with high scores of 6 and 9 out of 10. The reviewers had also provided us with valuable feedback.
Reviews, Rebuttal, and Reprise
On the early morning of 3rd May, we recieved our preliminary reviews for the paper. We had gotten a 3, 4, and 4 out of 6. The reviews were very critical and raised a lot of valid concerns. Luckily, we were able to justify our position, ran some additional experiments, and drafted a solid rebuttal with the help of Professors. This was followed by about a month of nervous waiting for the final reviews and decisions.
On the morning of June 18th 2026, we recieved an email saying that our paper was accepted. Two of the reviewers had increased their scores, finally resulting in the scores 5, 4, and 4 out of 6. I was very thrilled by this news and excited at the opportunity of attending one of the best ML conferences in the world.
The journey, which spanned a year, had not ended but just begun, with this paper acceptance being an important milestone to be remembered. The caffiene fueled nights, the long weekly meetings, late night discussions with labmates, solid advice from seniors, and the chaotic paper writing with coauthors had just become highly cherished memories.
From a friend jokingly suggesting applying for a lab, to the paper acceptance at ECCV, it had been a long, fulfilling road filled with ups and downs. Nonetheless, I am happy to have taken it. To add to this, I got the news that my previously suspended project, Pragyan, had been adopted by ANRF and was actively being used to evaluate grant proposals!
The Conference
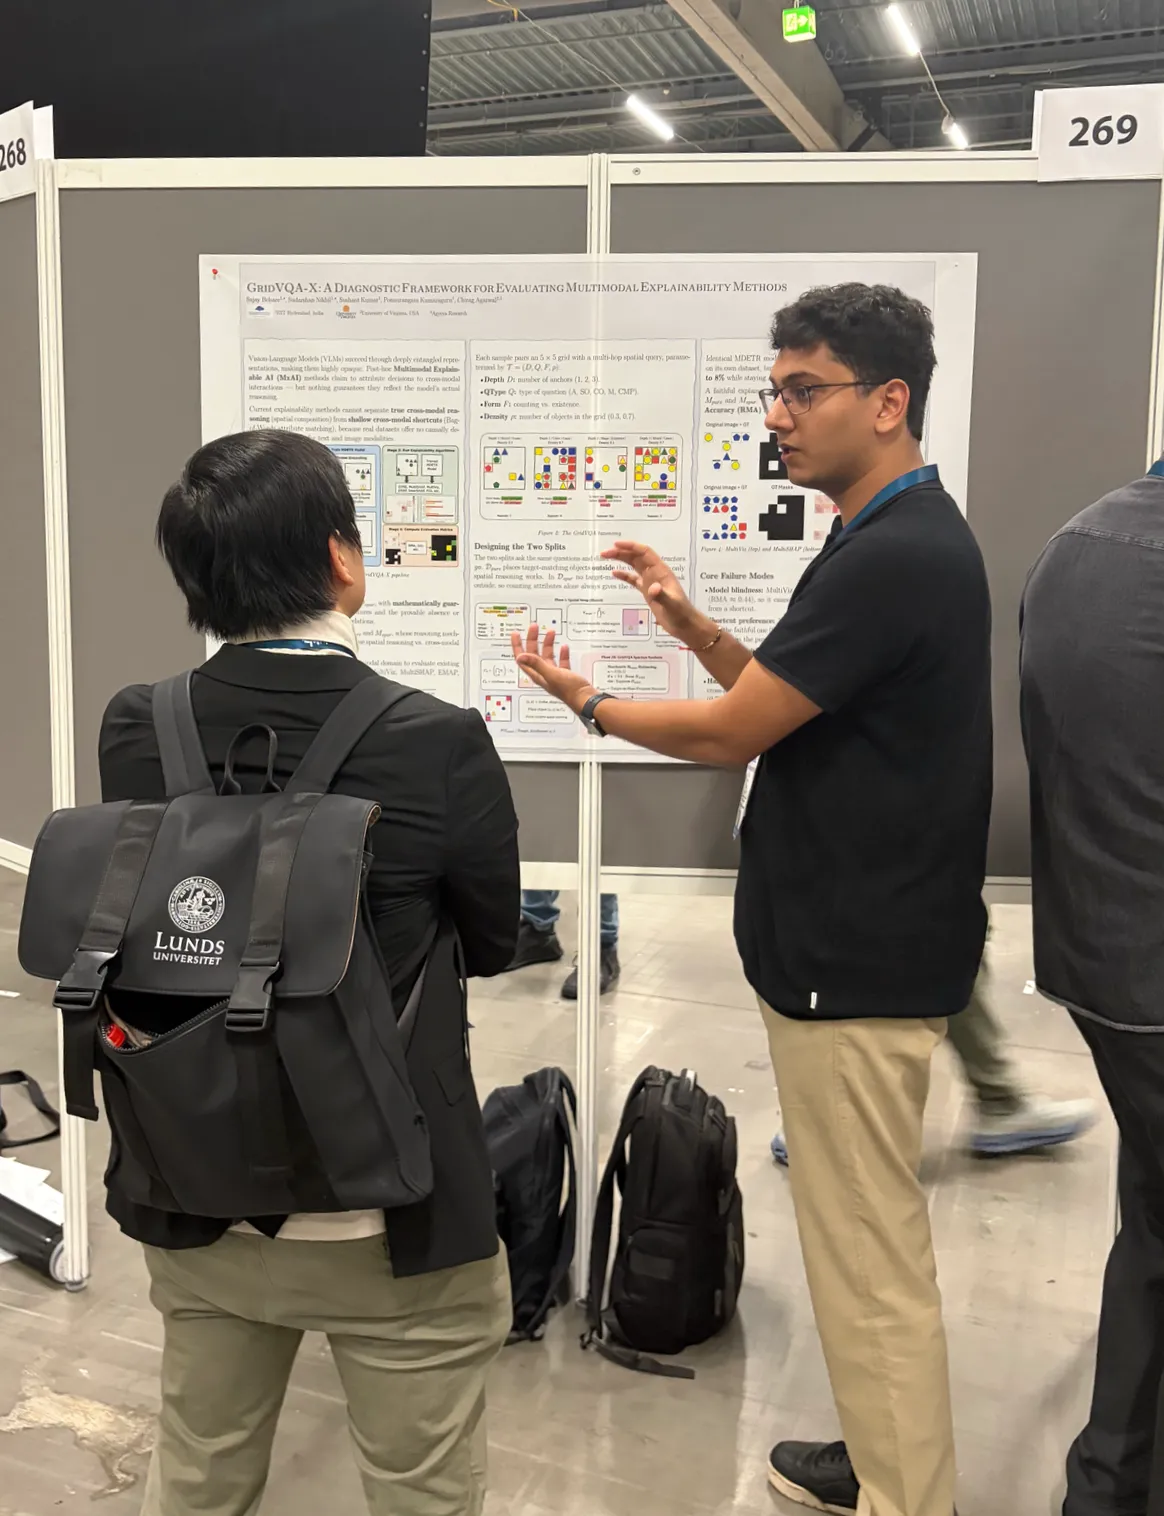
The experiences and conversations I had at ECCV deserve to be a blog of their own, but I would like to remark that some of the most motivated, and highly knowledgable people were present there. It had really given me a new perprestive on research and motivated me to continue working on challenging research problems.
Here are some of the pictures I clicked during the conference:
Thank you for reading the blog!